
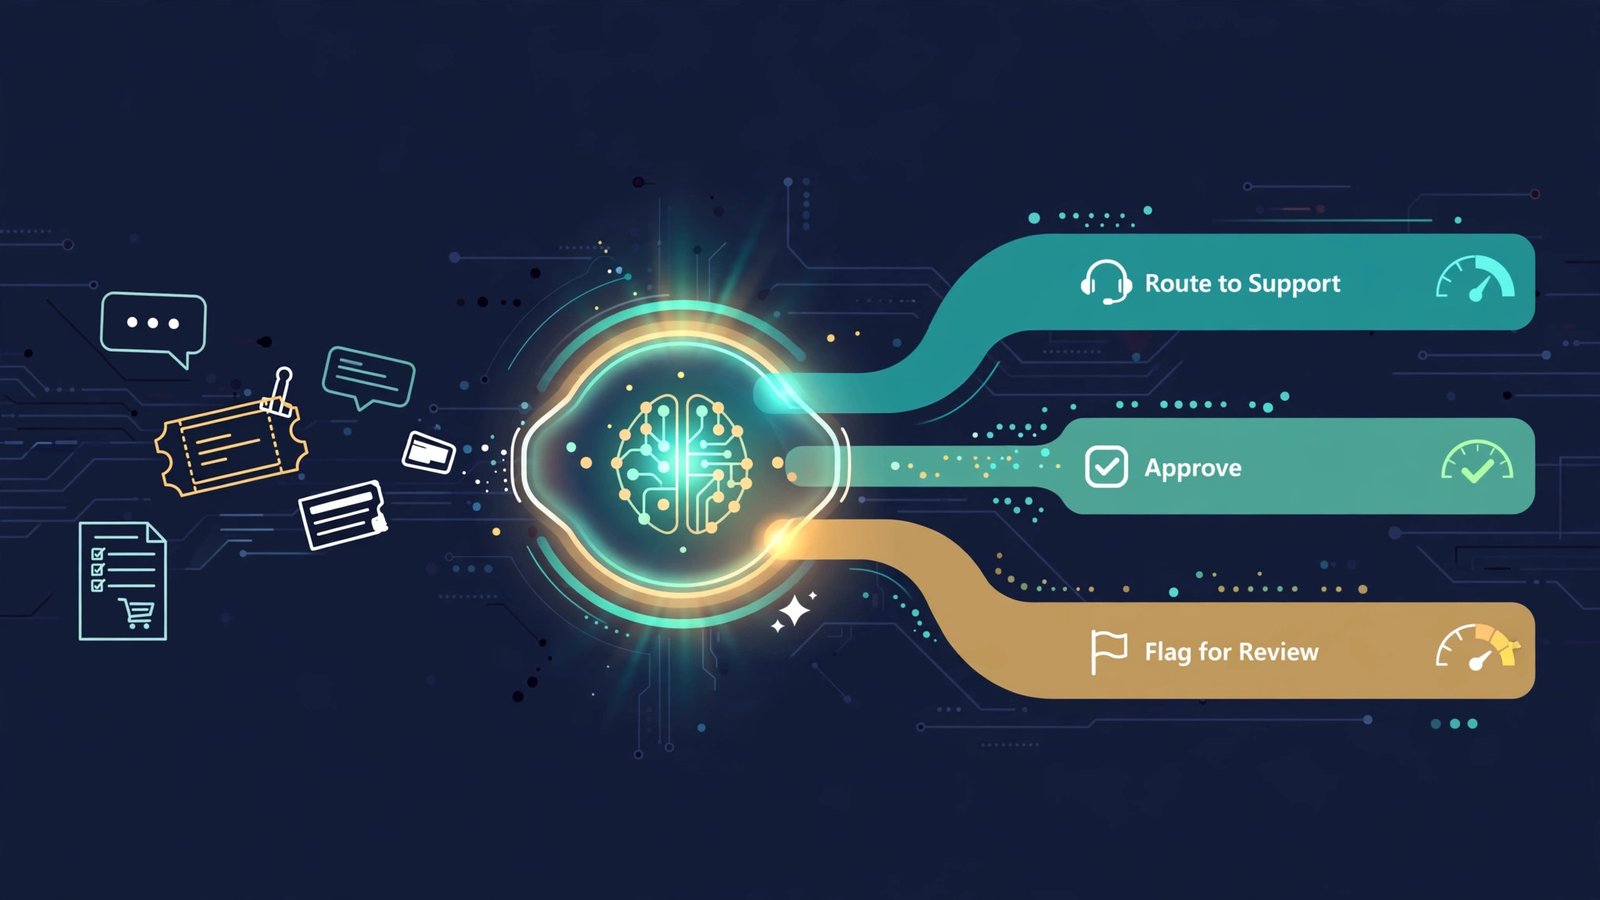
On October 22, 2026, OpenAI took its Decisions API out of public beta and into general availability. If you missed the beta (we covered it when it launched on October 6), here’s the one-line version: instead of asking an AI model to write you a paragraph and then parsing the answer with code, this API answers your app’s questions with a number or a label — a probability, a pick from your list, or a rubric score. No prose. No output tokens. And because there’s nothing to decode, OpenAI says it answers about 10x faster than its regular Responses API.
The price is what makes it a small-business story rather than a developer story: $0.10 per million input tokens, $0.01 per million cached input tokens, and zero output-token charges. To put that in real money, sorting 10,000 support tickets costs about $0.50. That’s not a typo. Fifty cents.
But the headline number is also the part most coverage gets wrong by omission. The price only works for a specific kind of job, the speed claim is OpenAI’s own benchmark, and the “decisions” it returns are probabilities — not verdicts. This article is the full picture: what changed at GA, the real cost math for five small-business use cases, who should switch this week, and the honest caveats that decide whether this saves you money or quietly misroutes your customers.
What general availability actually changed on October 22
The Decisions API had a short life in beta — just 16 days. Public beta opened October 6, and limited preview was only shown at DevDay on September 29. For GA, OpenAI shipped real upgrades, not just a status change:
- More work per request. One request can now carry up to 400 questions (the beta ceiling was lower). Since you’re billed per input token regardless, batching 400 micro-decisions into one call cuts your request count dramatically — 10,000 support tickets is just 25 API calls.
- New input types. The beta took text and images; GA adds structured JSON input, so you can feed database rows or webhook payloads straight in without formatting them as sentences first.
- Prompt caching. Repeated system instructions get cached at $0.01/M cached input, a 90% discount on the tokens you send over and over.
- Native GPT-Live integration. A voice session can call the Decisions endpoint mid-conversation — the AI listens to the caller and quietly classifies intent while it talks. That matters for small businesses running phone or chat front desks.
- Simpler account tiers. OpenAI collapsed its five API usage tiers into three: Build ($5 in total credit purchases, $500/month usage limit), Launch ($100, $5,000/month), and Grow ($500, $200,000/month), with a free tier at a $100 monthly limit. Organizations move up automatically as they spend.
Under the hood it’s still one model: gpt-6-luna, the smallest of the GPT-6 family (launched September 22 alongside GPT-6 Sol). The endpoint is POST /v1/decisions, and there’s a visual playground at platform.openai.com/decisions where you can test questions before writing code. On the compliance side, the API supports Zero Data Retention and HIPAA eligibility, with regional processing in the US and Europe — which is what makes it plausible for health-adjacent and finance-adjacent workflows that cheaper experimental tools can’t touch.
Early adopters named in the announcement include Box, Datadog, Ramp, Sierra, and Speak — mostly doing exactly what you’d expect: document classification, request routing, and transaction categorization at volume.
How it works in plain English: a judge, not a writer
A normal LLM is a writer. You ask, it writes paragraphs, and your code digs the answer out. The Decisions API is a judge. You define the decision ahead of time, send the evidence, and get back a structured answer your code can act on immediately. There are exactly three answer shapes:
- Predicate — a probability from 0 to 1 that a condition is true. (“Is this customer likely to cancel?” → 0.83.)
- Choice — a pick from a fixed list you supply, with confidence scoring. (“Which queue gets this ticket?” → billing.)
- Score — a rating against ordered levels you define, computed as a probability-weighted average — so it can land between levels. OpenAI’s own docs example uses three severity levels numbered 0–2, where probabilities of 0.1, 0.7, and 0.2 produce a score of 1.1.
That last detail is worth pausing on, because it reveals what this API really is: it never tells you something is true. It tells you how much the evidence points that way, and you set the threshold. OpenAI’s guide is explicit about this — it tells developers to calibrate thresholds from labeled examples in their own application, weighing the cost of false positives against false negatives. A spam filter that wrongly blocks a paying customer costs more than one that lets a spam email through; your threshold should know that.
The money math: what a decision really costs at $0.10/M
This is the part nobody’s headline gives you. Here’s worked math for five realistic small-business volumes, using $0.10 per million input tokens and conservative token counts (a token is roughly 3–4 English characters):
| Job | Tokens per decision | Monthly volume | Input tokens | Monthly API cost |
|---|---|---|---|---|
| Support ticket routing | ~500 | 10,000 tickets | 5M | $0.50 |
| Support ticket routing (scaling up) | ~500 | 100,000 tickets | 50M | $5.00 |
| Sales lead scoring | ~800 | 2,000 leads | 1.6M | $0.16 |
| Customer review triage | ~300 | 500 reviews | 150K | ~$0.02 |
| Invoice/expense categorization | ~1,200 | 400 invoices | 480K | ~$0.05 |
Now set that against what the same work costs today. A freelance virtual assistant charging $6/hour handles roughly 30 tickets an hour — so routing 10,000 tickets costs about $2,000 in VA time versus $0.50 in API compute. That’s a 4,000x gap, and it’s not really a comparison between people and AI — it’s a comparison between paying humans to read and paying a model to decide, so the human can spend their time on the tickets that actually need judgment.
For calibration, independent testers have run the numbers. The AI helpdesk company eesel ran Luna through 20 support tickets twice across four setups and found routing cost $0.047 per 1,000 tickets — but with an important asterisk: on 7 of 40 calls, the model said a ticket was safe to auto-reply to when it wasn’t. A YouTube tester who ran 10,000 short tickets through three decision APIs computed roughly $0.96 on OpenAI’s endpoint — the same ballpark as my math (the difference is just ticket length). The takeaway from both tests is the same: the compute is essentially free; the thing you’re buying with your attention is the error rate.
And one more comparison, because it matters for the “should I just use the regular API” question: the same gpt-6-luna model through OpenAI’s standard endpoints costs $0.10/M input plus $0.50/M output. A classification job through the Responses API that writes a 100-token answer per ticket pays for output you never wanted. The Decisions API deletes that line item entirely — which is why one pricing analyst estimated it cuts classification workloads to roughly one-fifth of what standard Luna pricing implies.
Two billing fine-print items, because sources genuinely conflict on one of them: cached input is $0.01/M (a 90% discount for repeated prompts), and GA-era coverage says cache writes are charged while some beta-era reports said they were free. OpenAI’s current pricing page is the authority here — check it before you budget, because cache-write billing on large batch jobs is the only line item that could surprise you.
The video above is worth your ten minutes: an independent tester ran 8 fictional support tickets through the endpoint with the answer key locked before the first call, then scored every answer honestly. Result: 8/8 answered, 7 matched the locked label, 1 was an accepted alternative, 5 auto-routed and 3 sent to a human. Total computed cost for the whole test: about $0.0003. I like this test because the tester did the two things most demos skip: they locked the answer key first (no moving the goalposts), and they disclosed that 8 fake tickets are not a benchmark.
Who should switch this week — and who shouldn’t
Not every AI job is a decision job. Here’s the framework:
Switch (or start building) if you have:
- High-volume classification. Support queues, content moderation, spam filtering, review triage — anything where a human reads 100+ items a day and most of them sort into fewer than ten buckets.
- Latency-sensitive gating. Fraud checks, payment approvals, access decisions — places where a 150ms answer changes the product and a 2-second paragraph doesn’t fit. (The 10x speed claim is OpenAI’s own measurement against its Responses API, ~100–180ms typical. No independent benchmark exists yet — more on that below.)
- Compliance requirements. Zero Data Retention and HIPAA eligibility make this the rare cheap endpoint that doesn’t require you to choose between compliance and cost.
- An existing Luna workload. If you’re already classifying with gpt-6-luna through the Responses API, this is a straight cost and speed upgrade for the same model.
Hold off if you have:
- Jobs that need prose back. If the output needs extracted fields, a written summary, or an explanation for the user, OpenAI points you at Structured Outputs on the Responses API instead. This endpoint will never write you a sentence.
- Chained decisions. Each dependent step is a separate request, so latency stacks. Five sequential decisions at 150ms each is 750ms — fine; five sequential decisions each needing the last one’s output plus your code in between is a different architecture question.
- No labeled history. The API’s own guidance is blunt: thresholds set without your own labeled examples are guesses. If you can’t show it 50–100 examples of how you’ve sorted things in the past, you don’t have a calibrated decision system — you have a random number generator with nice branding.
- Tiny volume. At $0.50/month for 10,000 tickets, cost isn’t the blocker — integration effort is. If you get 40 tickets a month, your time building the integration costs more than the thing you’re automating. Do the 400-ticket-a-day math first.
The honest caveats the $0.10 headline doesn’t mention
The price is real. These are real too — and they matter more than the price.
The probabilities aren’t calibrated the way you’d hope. The word “probability” suggests something mathematically disciplined, but independent tests paint a messier picture. A tester on OpenAI’s own developer forum ran 1,000 calls on a coin weighted to land heads 70% of the time: the yes/no predicate question came back “yes” about 70% of the time (nicely calibrated), but the pick-one question returned “heads” on 98% of calls. And in a marble test, swapping the order of the choices moved “red” from 86% to 73%. In plain terms: the number you get back is sensitive to how you ask, not just to the evidence. That’s exactly why the docs tell you to calibrate against your own labeled data — the number means something only after you’ve measured it on your own distribution.
Developers testing head-to-head are split, and the honest ones say so. When the API went to beta, one developer posting as “jefff” ran a few hundred questions through both OpenAI’s Decisions API and TypeSafe’s rival Jev ($0.042/M input, about half the price). Jev came out more accurate on nuanced judgment calls and faster in his test — but jefff added his own caveat, which I want to quote in spirit because it’s the right way to read any early test: treat it as a strong early signal rather than a general benchmark. Meanwhile, in a 24-test-case customer-support demo, another tester found the text results close between the two, with Jev’s lower price winning for text-only jobs and OpenAI’s image support opening use cases Jev couldn’t touch. The market is genuinely competitive — Jev, Perplexity’s Open Decider, Cloudflare’s Clef, and AWS’s Strands Decider all launched within weeks of each other — and OpenAI doesn’t have a decisive accuracy lead. It has a price lead, a compliance lead, and a distribution lead. Don’t confuse the three.
The speed claim is self-measured. “About 10x faster than the Responses API” compares OpenAI to itself, on its own hardware, with no published methodology. The 100–180ms figures floating around are user-reported, not OpenAI-published. It’s plausible — skipping output generation removes the slowest part of inference — but no third party has published a proper benchmark, and your latency will include your network, your region, and your prompt length. Budget for 2–3x the claimed number and you’ll rarely be disappointed.
The wrong decision is the expensive part. Go back to that eesel test: Luna routed every ticket correctly and cost half a cent per thousand — and still said “safe to auto-reply” on 7 of 40 tickets that weren’t. At 100,000 tickets a month, a 17.5% false-positive rate on auto-actions is 17,500 wrong auto-replies. This is why the right architecture is route, don’t act: let the API sort into queues and flag confidence levels, and keep humans on anything below your threshold. The endpoint is a triage nurse, not a surgeon. Budget for the human review lane before you budget for the API — the API costs $5, the review lane is the real line item.
The tier math deserves a glance. Under the new Build/Launch/Grow tiers, a business doing the $5/month ticket-routing workload sits comfortably in Build ($500/month limit). But batch-heavy JSON jobs with large prompts and image inputs burn faster than the headline $0.10/M suggests — the regional processing premiums and long-context multipliers mentioned in the docs apply on top. At small volumes none of this matters; at a million decisions a month, read the pricing page like a contract.
Getting started: a one-afternoon checklist
If the framework above says this is for you, here’s the whole setup:
- Open the playground (platform.openai.com/decisions) and write your three questions: one predicate, one choice, one score. Keep the choice list short — five options calibrate better than fifteen.
- Build a labeled set of 50–100 real examples from your own history. This is the step everyone skips and the step that determines whether the system works. Sort them the way you’ve always sorted them; that’s your ground truth.
- Run the set and set thresholds from the results. Start conservative: auto-act only above 0.9 confidence, human review between 0.6 and 0.9, manual below 0.6. You’ll tighten these as you measure.
- Route first, act later. Point the API at queue assignment and prioritization — decisions that are cheap to reverse — before you let it touch anything customer-facing.
- Measure for two weeks, then decide. Track: routing accuracy against your labeled set, false-positive rate on the auto-act lane, and actual API spend. If accuracy holds above 90% and the human review lane stays under 20% of volume, expand. If not, your questions need rewriting, not your budget.
One architecture tip from the GA feature set: use the 400-question batching aggressively. Don’t call the API once per ticket from your webhook — collect a batch and send 400 decisions in one request. It’s the same token price with a fraction of the request overhead, and it’s the difference between a system that scales and one that rate-limits itself.
The bottom line
The Decisions API is the clearest sign yet of where the AI API business is going: the frontier models (GPT-6 Sol, Luna, and Astra, which we priced out last month) keep getting cheaper, and the new money is in shaped intelligence — models that return the exact data structure your code needs instead of a paragraph you have to mine. For small businesses, that shape is the whole value proposition: you don’t need a prompt engineer, you need a triage layer that costs less than your coffee budget and answers in milliseconds.
But the honest version of this story has two sentences, not one. The first: sorting 10,000 support tickets for $0.50 is real, and it’s GA today. The second: the $0.50 endpoint is only as good as your labeled examples, your thresholds, and your discipline about keeping humans on the decisions that matter. Get those right and it’s the cheapest hire you’ll ever make. Get them wrong and you’ve automated your mistakes at 10x speed.
Sources: OpenAI Decisions API developer guide (GA announcement, Oct 22, 2026); Unite.AI coverage of the GA launch; eesel.ai’s pricing test (Oct 2026); fourweekmba.com’s price breakdown; community test reports from the OpenAI developer forum.
Frequently Asked Questions
How much does the OpenAI Decisions API cost?
$0.10 per million uncached input tokens and $0.01 per million cached input tokens, with no output-token charges. In real terms: about $0.50 to route 10,000 typical support tickets. Regional processing premiums and long-context multipliers can apply on top — check OpenAI’s current pricing page before budgeting a large deployment.
Is the Decisions API actually generally available?
Yes — GA arrived October 22, 2026, sixteen days after the October 6 public beta (previewed at DevDay on September 29). Any developer with API access can use POST /v1/decisions today.
What’s the difference between the Decisions API and the regular Chat/Responses API?
The Decisions API returns only typed answers — a probability, a choice from your list, or a rubric score — powered exclusively by gpt-6-luna. It generates no prose, so it’s roughly 10x faster (OpenAI’s claim) and you never pay for output tokens. Use the Responses API with Structured Outputs when you need written text or extracted fields back.
How many decisions can I send in one request?
Up to 400 questions per request at GA (raised from the beta limit). You can batch mixed question types — predicates, choices, and scores — in a single call.
Should a small business replace its VA or support tool with this?
No — not replace, augment. The right pattern is route, don’t act: let the API sort tickets, leads, or reviews into queues at $0.10/M input, and keep humans on anything below your confidence threshold. Independent tests show real (if small) error rates — one test found the model wrongly approved auto-replies on 7 of 40 tickets. Budget for a human review lane; that’s the real cost, not the API.
Do I need labeled examples to use it?
Effectively, yes. OpenAI’s own guide says to set thresholds from labeled examples in your own application, weighing false-positive vs false-negative costs. Without 50–100 examples of how you’ve sorted things before, any threshold you set is a guess — and the probability the API returns is only meaningful after you’ve calibrated it on your own data.